Academic / CourseworkMachine Learning~2 min read
Fake News Detector
University NLP classification project comparing Bidirectional LSTM architectures.
What I Built#
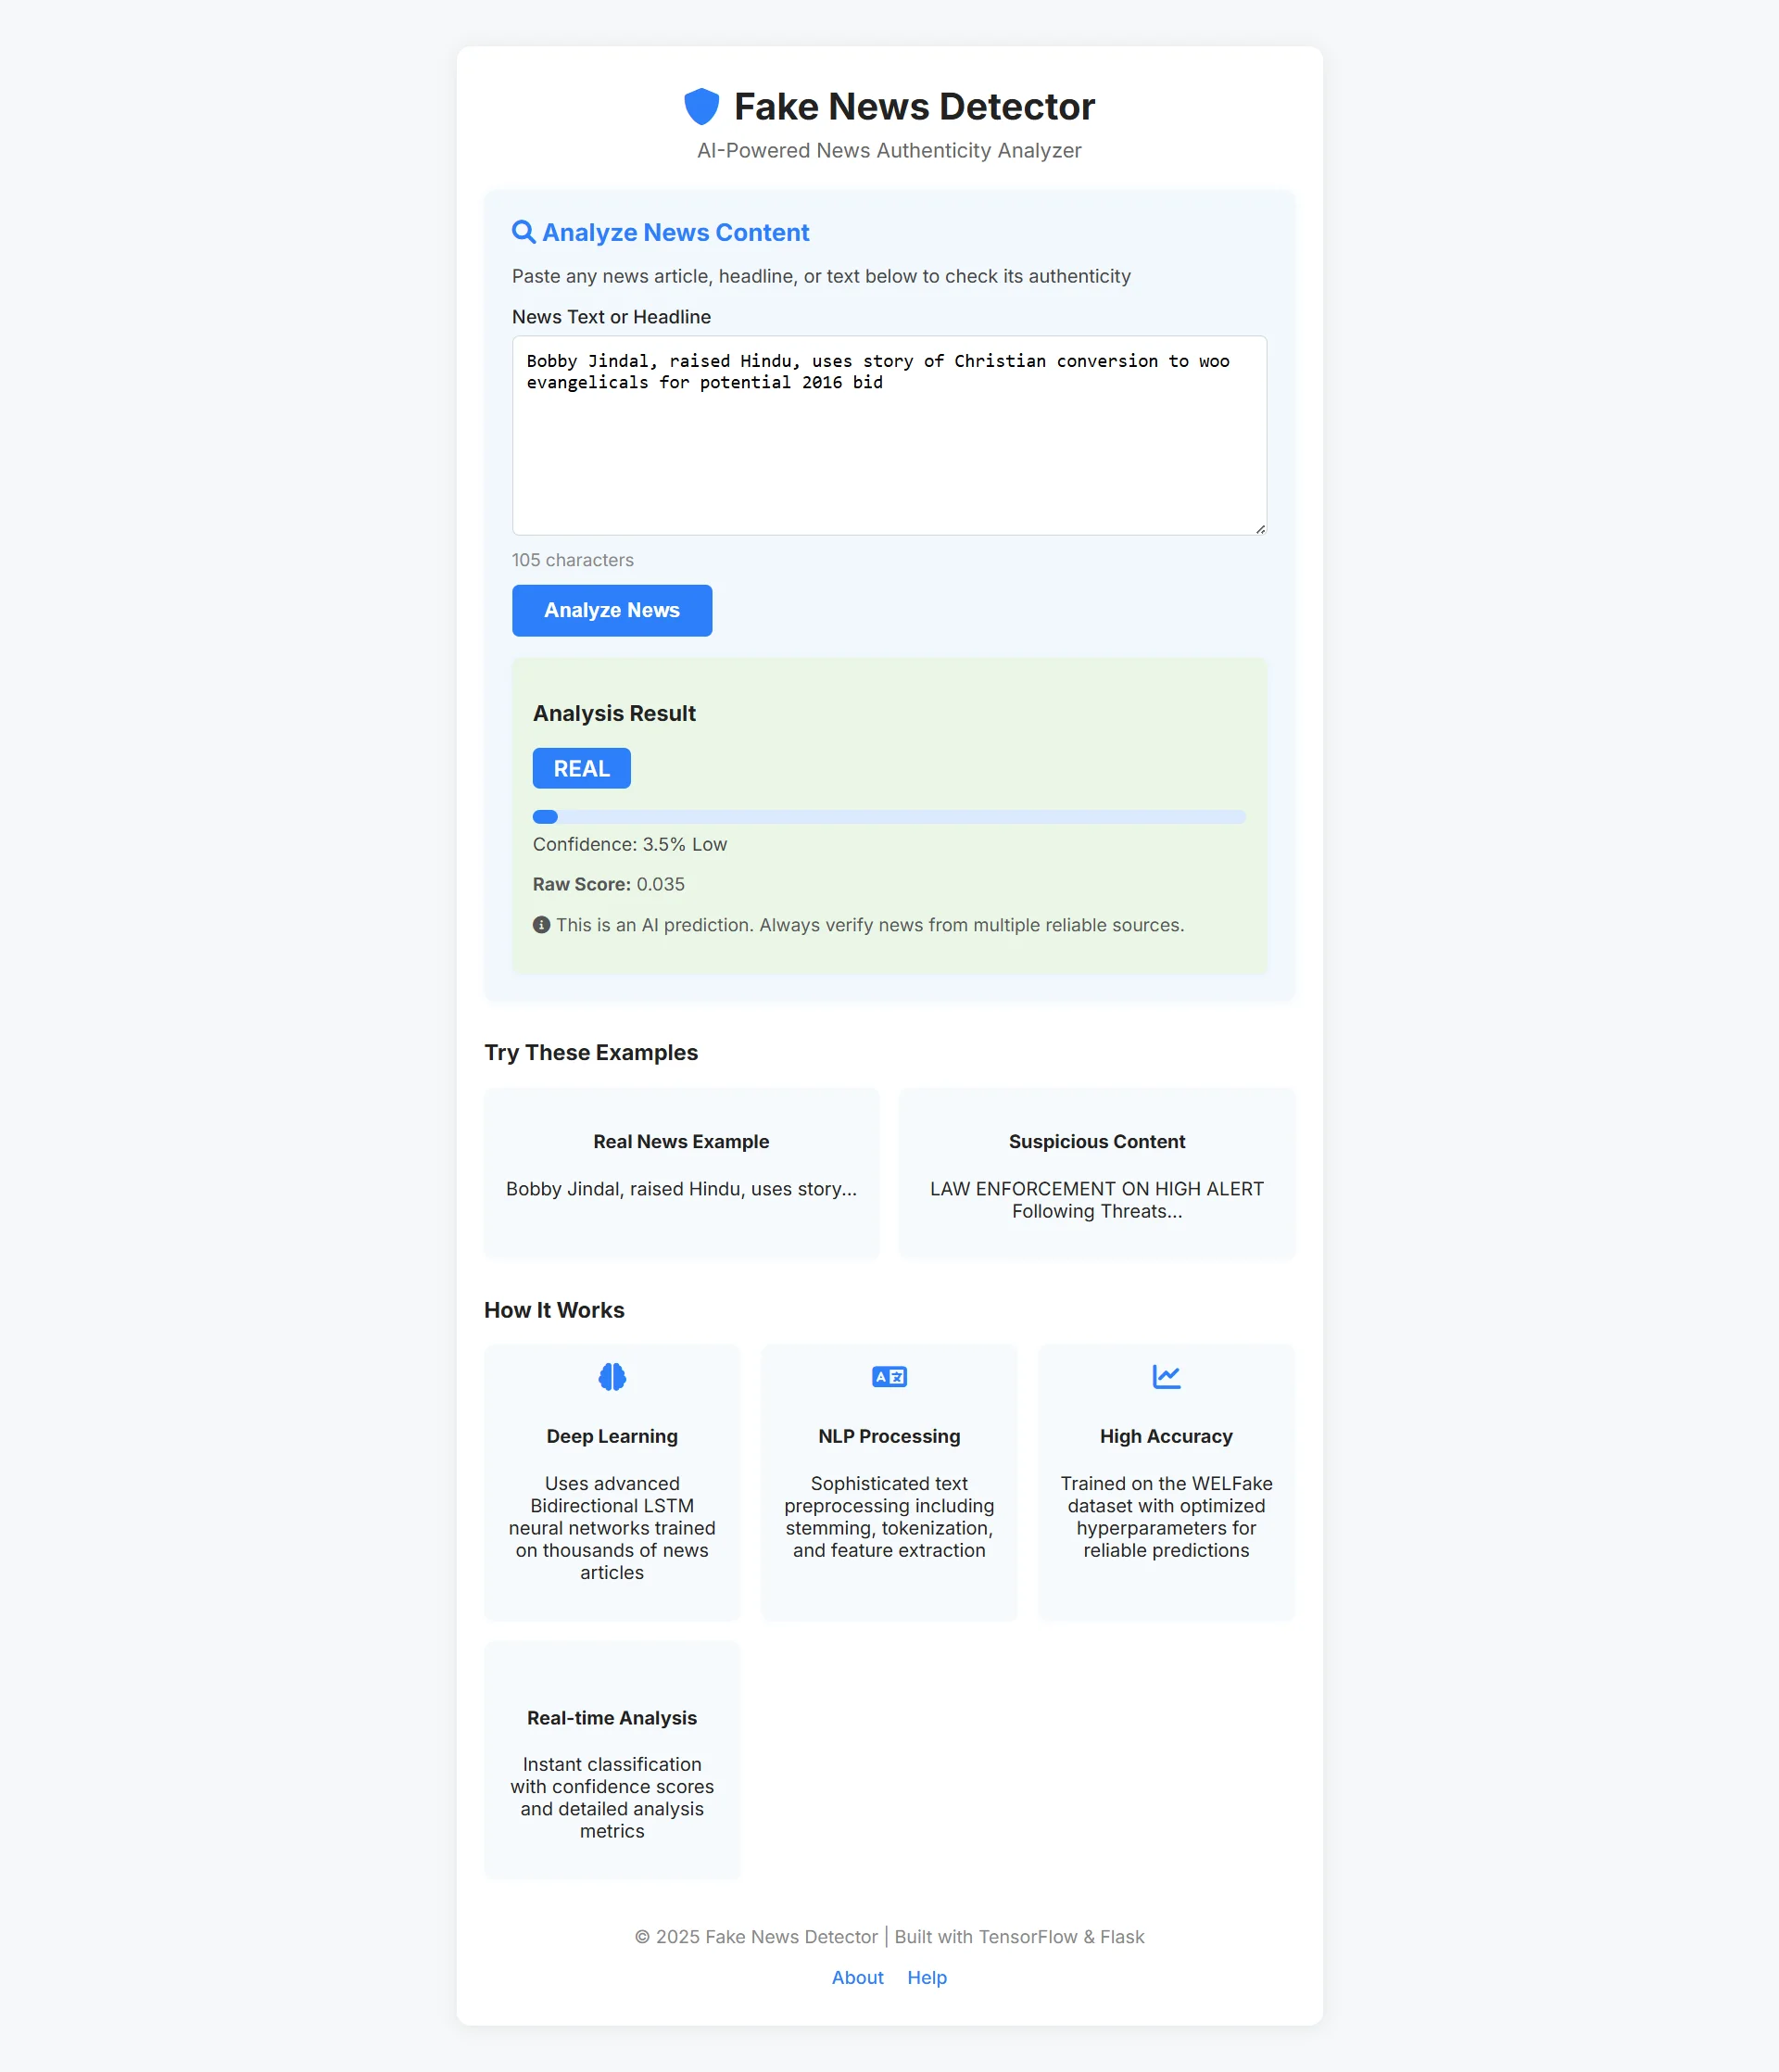
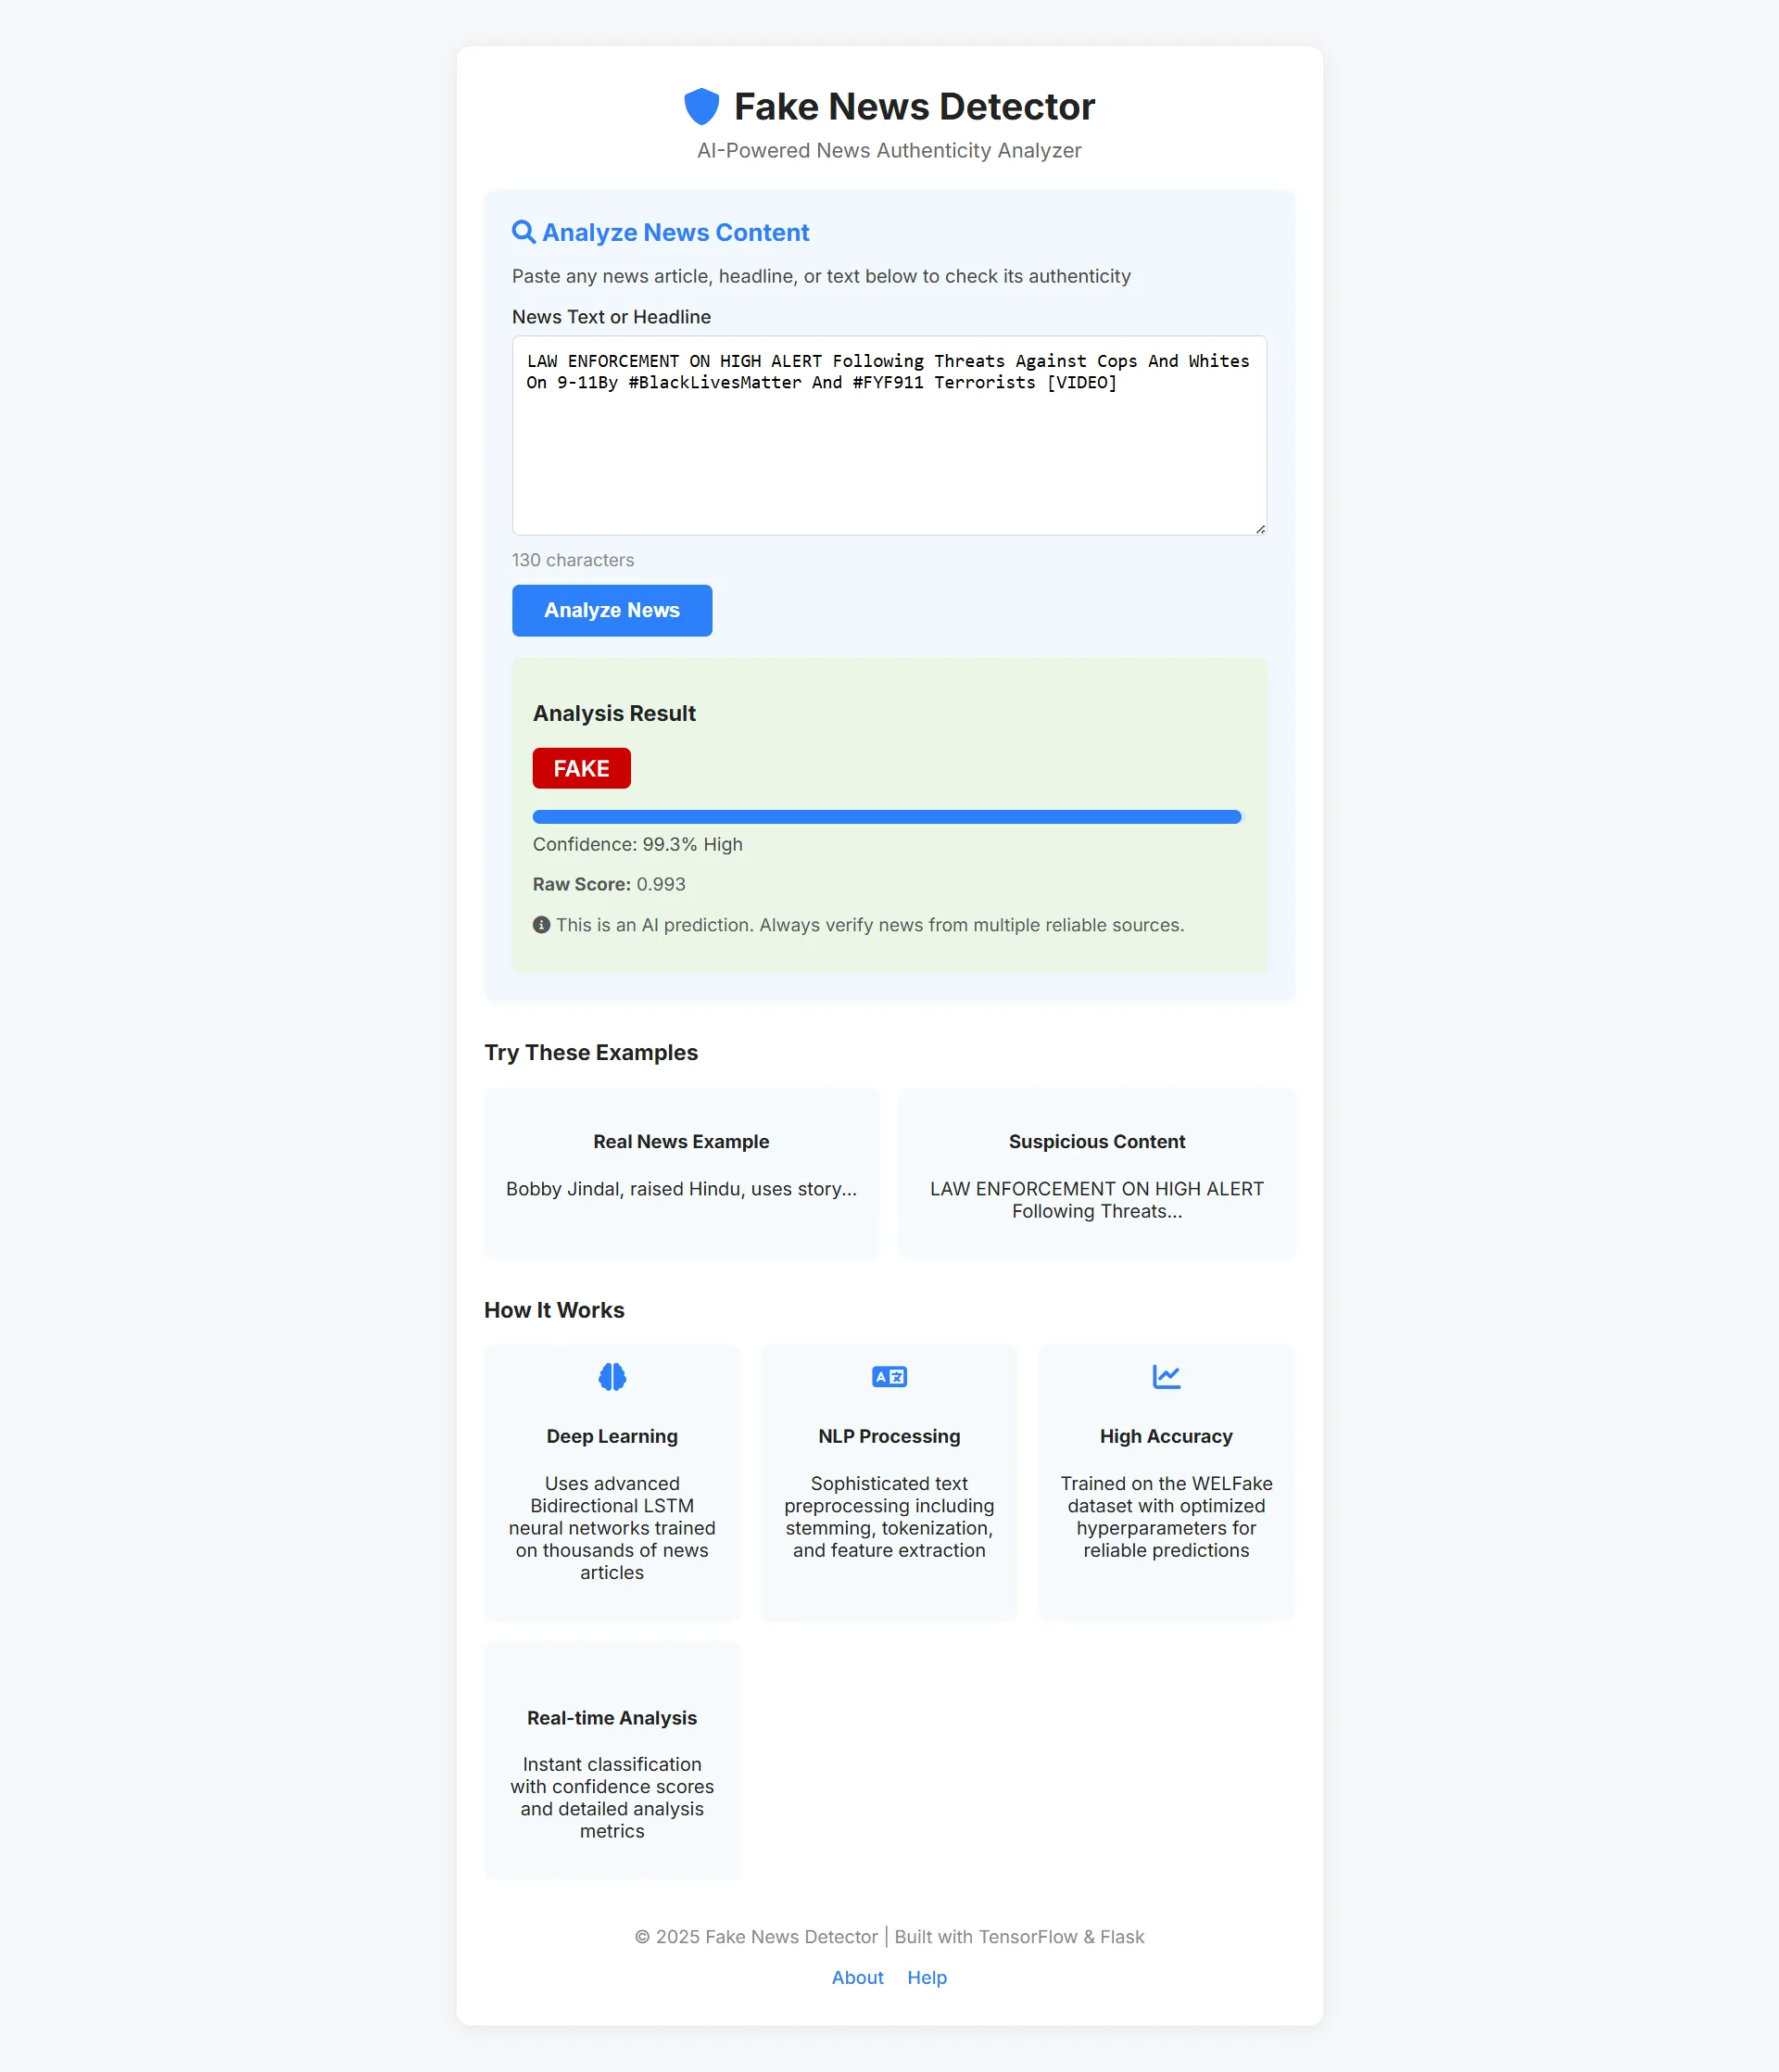
I built this project for a university machine learning course to explore deep learning for natural language classification. The goal was to train a binary classifier in Python using TensorFlow/Keras and NLTK that evaluates an article's headline and body text to predict whether it is genuine news or fabricated.
How the Pipeline Works#
architecture-diagram.txt
Raw Article Text
       │
       ▼
┌──────────────────────────────┐
│  Text Preprocessing (NLTK)   │ (Lowercasing, stopwords, lemmatization)
└──────────────┬───────────────┘
               │
               ▼
┌──────────────────────────────┐
│    Tokenization & Padding    │ (Sequences capped at 500 tokens)
└──────────────┬───────────────┘
               │
               ▼
┌──────────────────────────────┐
│   Keras Embedding Layer      │ (Dense word vectors)
└──────────────┬───────────────┘
               │
               ▼
┌──────────────────────────────┐
│   Bidirectional LSTM Layer   │ (Processes text forwards and backwards)
└──────────────┬───────────────┘
               │
               ▼
┌──────────────────────────────┐
│     Dense + Sigmoid Head     │ (Probability score: Real vs Fake)
└──────────────────────────────┘- 01Text Preprocessing: Raw articles are cleaned using NLTK by stripping HTML tags, removing punctuation and common stopwords, and lemmatizing words to their base forms.
- 02Tokenization & Sequence Padding: The cleaned text is tokenized into integer sequences and padded to a maximum length of 500 words.
- 03Word Embeddings: An embedding layer maps integer tokens into dense vector space, allowing the network to capture semantic relationships between words.
- 04Bidirectional LSTM: A
Bidirectional(LSTM(64))layer reads the sequence in both forward and backward directions. This helps capture linguistic context where later clauses modify the meaning of earlier statements. - 05Classification: A dense layer with 30% dropout and a sigmoid activation produces an authenticity score between 0 and 1.
Practical Lessons from the Project#
- Why Bidirectional LSTMs helped: Standard LSTMs read text strictly from left to right. Using bidirectional layers captured sensationalist phrases and qualifying statements at the end of sentences that standard left-to-right reading often diluted.
- Watch out for shortcut learning: In initial runs, the model achieved suspiciously high accuracy. When I checked the data, I found it had memorized journalist bylines and news agency tags (like "Reuters") in the opening lines. Stripping author names and publisher tags during preprocessing forced the network to evaluate actual writing tone instead.
- Capping sequence length: News articles vary widely in length, from 150 to over 3,000 words. Capping sequences at 500 tokens captured the headline and lead paragraphs where editorial bias is strongest, while preventing out-of-memory errors during training.
Complete Technology Stack
PythonTensorFlowBiLSTMNLTKScikit-learn